Vavr, Collections, and Java Stream API Collectors

Vavr is now a must-have for every modern Java 8+ project. It encourages writing code in a functional manner by providing a new persistent Collections API along with a set of new Functional Interfaces and monadic tools like Option, Try, Either, etc.

You can read more about it here.

Vavr’s Persistent Collections API

To provide useable immutable data structures, the whole Collections API needed to be redesigned from scratch.

The standard java.util.Collection interface contains methods that discourage immutability such as:

boolean add(E e);
boolean remove(Object o);
boolean addAll(Collection<? extends E> c);
boolean removeAll(Collection<?> c);

One might think that the problem is that those methods allow modifications of the particular collection instance, but this is not entirely true – with immutable data structures, each mutating operation needs to derive a new collection from the existing one. Simply put, each of those methods should be able to return a new instance of the collection.

Here, the whole collections hierarchy is restricted to returning boolean or void from mutating methods – which makes them suitable only for mutable implementations.

Of course, immutable implementations of java.util.Collection exist, but above-mentioned methods are simply forbidden. That’s how it looks like in the com.google.common.collect.ImmutableList:

/**
 * Guaranteed to throw an exception and leave the list unmodified.
 *
 * @throws UnsupportedOperationException always
 * @deprecated Unsupported operation.
 */
@Deprecated
@Override
public final void add(int index, E element) {
  throw new UnsupportedOperationException();
}

And this is far from perfect – even the simplest add() operation becomes a ceremony:

ImmutableList<Integer> original = ImmutableList.of(1);

List<Integer> modified = new ImmutableList.Builder<Integer>()
  .addAll(original)
  .add(2)
  .build();

A major redesign made it possible to interact with immutable collections more naturally and add some new exciting features:

import io.vavr.collection.List;
// ...

List<Integer> original = List.of(1);
List<Integer> modified = original.append(2);

modified.dropWhile(i -> i < 42);
modified.combinations();
modified.foldLeft(0 , Integer::sum)

Collecting Vavr’s Collections

One of the key features of the Java Stream API was the collect() API that made it possible to take elements from Stream and apply the provided strategy to them – in most cases that would be simply placing all elements in some collection.

Vavr’s collections have a method that provides the similar(but limited) functionality but it’s not being used often because almost all operations that were available only using Stream API, are available on the collection level in Vavr.

But… one of the method signatures of Vavr’s collect() is especially intriguing:

<R, A> R collect(java.util.stream.Collector<? super T, A, R> collector)

As you can see, Vavr’s collections are fully compatible with Stream API Collectors and we can use our favourite Collectors easily:

list.collect(Collectors.toList());
list.collect(Collectors.groupingBy(Integer::byteValue));

That might not be super useful for everyday use-cases because the most common operations are accessible without using Collectors but it’s comforting to know that Vavr’s functionality is a superset of Stream API’s (at least in terms of collect() semantics)

Collecting Everything

The interesting realization happens when we decide to investigate the type hierarchy in Vavr:
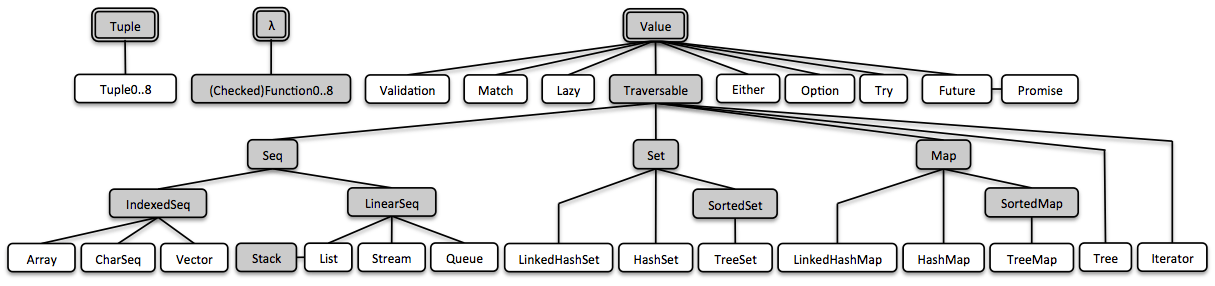
source: http://www.vavr.io/vavr-docs/

We can notice here that the Value resides on top collections hierarchy and this is where the collect() method mentioned above is defined.

If we look closer, it’s clear that classes like Option, Try, Either, Future, Lazy also implement the Value interface. The reasoning behind this is that they are all essentially containers for values – containers that can hold max up to one element.  

This makes them compatible with Stream API Collectors, as well:

Option.of(42)
  .collect(Collectors.toList());

Try.of(() -> URI.create("4comprehension.com"))
  .collect(Collectors.partitioningBy(URI::isAbsolute));

Summary

The redesign of the Collections API allowed the introduction of cool new methods, as well as achieving full interoperability with Java Stream API Collectors – which can also be applied to Vavr’s functional control structures like Option, Try, Either, Future, or Lazy.

The examples above use:

<dependency>
    <groupId>io.vavr</groupId>
    <artifactId>vavr-test</artifactId>
    <version>0.9.0</version>
</dependency>
You May Also Like

Thought static method can’t be easy to mock, stub nor track? Wrong!

No matter why, no matter is it a good idea. Sometimes one just wants to check or it's necessary to be done. Mock a static method, woot? Impossibru!

In pure Java world it is still a struggle. But Groovy allows you to do that really simple. Well, not groovy alone, but with a great support of Spock.

Lets move on straight to the example. To catch some context we have an abstract for the example needs. A marketing project with a set of offers. One to many.

import spock.lang.Specification

class OfferFacadeSpec extends Specification {

    OfferFacade facade = new OfferFacade()

    def setup() {
        GroovyMock(Project, global: true)
    }

    def 'delegates an add offer call to the domain with proper params'() {
        given:
            Map params = [projId: projectId, name: offerName]

        when:
            Offer returnedOffer = facade.add(params)

        then:
            1 * Project.addOffer(projectId, _) >> { projId, offer -> offer }
            returnedOffer.name == params.name

        where:
            projectId | offerName
            1         | 'an Offer'
            15        | 'whasup!?'
            123       | 'doskonała oferta - kup teraz!'
    }
}
So we test a facade responsible for handling "add offer to the project" call triggered  somewhere in a GUI.
We want to ensure that static method Project.addOffer(long, Offer) will receive correct params when java.util.Map with user form input comes to the facade.add(params).
This is unit test, so how Project.addOffer() works is out of scope. Thus we want to stub it.

The most important is a GroovyMock(Project, global: true) statement.
What it does is modifing Project class to behave like a Spock's mock. 
GroovyMock() itself is a method inherited from SpecificationThe global flag is necessary to enable mocking static methods.
However when one comes to the need of mocking static method, author of Spock Framework advice to consider redesigning of implementation. It's not a bad advice, I must say.

Another important thing are assertions at then: block. First one checks an interaction, if the Project.addOffer() method was called exactly once, with a 1st argument equal to the projectId and some other param (we don't have an object instance yet to assert anything about it).
Right shit operator leads us to the stub which replaces original method implementation by such statement.
As a good stub it does nothing. The original method definition has return type Offer. The stub needs to do the same. So an offer passed as the 2nd argument is just returned.
Thanks to this we can assert about name property if it's equal with the value from params. If no return was designed the name could be checked inside the stub Closure, prefixed with an assert keyword.

Worth of  mentioning is that if you want to track interactions of original static method implementation without replacing it, then you should try using GroovySpy instead of GroovyMock.

Unfortunately static methods declared at Java object can't be treated in such ways. Though regular mocks and whole goodness of Spock can be used to test pure Java code, which is awesome anyway :)No matter why, no matter is it a good idea. Sometimes one just wants to check or it's necessary to be done. Mock a static method, woot? Impossibru!

In pure Java world it is still a struggle. But Groovy allows you to do that really simple. Well, not groovy alone, but with a great support of Spock.

Lets move on straight to the example. To catch some context we have an abstract for the example needs. A marketing project with a set of offers. One to many.

import spock.lang.Specification

class OfferFacadeSpec extends Specification {

    OfferFacade facade = new OfferFacade()

    def setup() {
        GroovyMock(Project, global: true)
    }

    def 'delegates an add offer call to the domain with proper params'() {
        given:
            Map params = [projId: projectId, name: offerName]

        when:
            Offer returnedOffer = facade.add(params)

        then:
            1 * Project.addOffer(projectId, _) >> { projId, offer -> offer }
            returnedOffer.name == params.name

        where:
            projectId | offerName
            1         | 'an Offer'
            15        | 'whasup!?'
            123       | 'doskonała oferta - kup teraz!'
    }
}
So we test a facade responsible for handling "add offer to the project" call triggered  somewhere in a GUI.
We want to ensure that static method Project.addOffer(long, Offer) will receive correct params when java.util.Map with user form input comes to the facade.add(params).
This is unit test, so how Project.addOffer() works is out of scope. Thus we want to stub it.

The most important is a GroovyMock(Project, global: true) statement.
What it does is modifing Project class to behave like a Spock's mock. 
GroovyMock() itself is a method inherited from SpecificationThe global flag is necessary to enable mocking static methods.
However when one comes to the need of mocking static method, author of Spock Framework advice to consider redesigning of implementation. It's not a bad advice, I must say.

Another important thing are assertions at then: block. First one checks an interaction, if the Project.addOffer() method was called exactly once, with a 1st argument equal to the projectId and some other param (we don't have an object instance yet to assert anything about it).
Right shit operator leads us to the stub which replaces original method implementation by such statement.
As a good stub it does nothing. The original method definition has return type Offer. The stub needs to do the same. So an offer passed as the 2nd argument is just returned.
Thanks to this we can assert about name property if it's equal with the value from params. If no return was designed the name could be checked inside the stub Closure, prefixed with an assert keyword.

Worth of  mentioning is that if you want to track interactions of original static method implementation without replacing it, then you should try using GroovySpy instead of GroovyMock.

Unfortunately static methods declared at Java object can't be treated in such ways. Though regular mocks and whole goodness of Spock can be used to test pure Java code, which is awesome anyway :)

Multi phased processing in scala

Last time in our project we had to add progress bar for visualization of long time running process. Process was made of a few phases and we had to print in which phase we currently are. In first step we conclude that we need to create a class of Progre...

Zookeeper + Curator = Distributed sync

An application developed for one of my recent projects at TouK involved multiple servers. There was a requirement to ensure failover for the system’s components. Since I had already a few separate components I didn’t want to add more of that, and since there already was a Zookeeper ensemble running - required by one of the services, I’ve decided to go that way with my solution.

What is Zookeeper?

Just a crude distributed synchronization framework. However, it implements Paxos-style algorithms (http://en.wikipedia.org/wiki/Paxos_(computer_science)) to ensure no split-brain scenarios would occur. This is quite an important feature, since I don’t have to care about that kind of problems while using this app. You just need to create an ensemble of a couple of its instances - to ensure high availability. It is basically a virtual filesystem, with files, directories and stuff. One could ask why another filesystem? Well this one is a rather special one, especially for distributed systems. The reason why creating all the locking algorithms on top of Zookeeper is easy is its Ephemeral Nodes - which are just files that exist as long as connection for them exists. After it disconnects - such file disappears.

With such paradigms in place it’s fairly easy to create some high level algorithms for synchronization.

Having that in place, it can safely integrate multiple services ensuring loose coupling in a distributed way.

Zookeeper from developer’s POV

With all the base services for Zookeeper started, it seems there is nothing else, than just connect to it and start implementing necessary algorithms. Unfortunately, the API is quite basic and offers files and directories abstractions with the addition of different node type (file types) - ephemeral and sequence. It is also possible to watch a node for changes.

Using bare Zookeeper is hard!

Creating connections is tedious - and there is lots of things to take care of. Handling an established connection is hard - when establishing connection to ensemble, it’s necessary to negotiate a session also. During the whole process a number of exceptions can occur - these are “recoverable” exceptions, that can be gracefully handled and not break the connection.

    class="c8"><span>So, Zookeeper API is hard.</span></p><p class="c1"><span></span></p><p class="c8"><span>Even if one is proficient with that API, then there come recipes. The reason for using Zookeeper is to be able to implement some more sophisticated algorithms on top of it. Unfortunately those aren&rsquo;t trivial and it is again quite hard to implement them without bugs.</span>

And since distributed systems are hard, why would anyone want another difficult to handle tool?

Enter Curator

<p
    class="c8"><span>Happily, guys from Netflix implemented a nice abstraction for dealing with Zookeeper internals. They called it Curator and use it extensively in the company&rsquo;s environment. Curator offers consistent API for Zookeeper&rsquo;s functionality. It even implements a couple of recipes for distributed systems.</span>

File read/write

<p
    class="c8"><span>The basic use of Zookeeper is as a distributed configuration repository. For this scenario I only need read/write capabilities, to be able to write and read files from the Zookeeper filesystem. This code snippet writes a sample json to a file on ZK filesystem.</span>

<a href="#"
                                                                                                  name="0"></a>

EnsurePath ensurePath = new EnsurePath(markerPath);
ensurePath.ensure(client.getZookeeperClient());
String json = “...”;
if (client.checkExists().forPath(statusFile(core)) != null)
     client.setData().forPath(statusFile(core), json.getBytes());
else
     client.create().forPath(statusFile(core), json.getBytes());


Distributed locking

Having multiple systems there may be a need of using an exclusive lock for some resource, or perhaps some big system requires it’s components to synchronize based on locks. This “recipe” is an ideal match for those situations.

ref="#"
                                                                                    name="b0329bbbf14b79ffaba1139881914aea887ef6a3"></a>


lock = new InterProcessSemaphoreMutex(client, lockPath);
lock.acquire(5, TimeUnit.MINUTES);
… do sth …
lock.release();


 (from https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/LockingRemotely.java)

Sevice Advertisement

<p

    class="c8"><span>This is quite an interesting use case. With many small services on different servers it is not wise to exchange ip addresses and ports between them. When some of those services may go down, while other will try to replace them - the task gets even harder. </span>

That’s why, with Zookeeper in place, it can be utilised as a registry of existing services.

If a service starts, it registers into the ServiceRegistry, offering basic information, like it’s purpose, role, address, and port.

Services that want to use a specific kind of service request an access to some instance. This way of configuring easily decouples services from their configuration.

Basically this scenario needs ? steps:

<span>1. Service starts and registers its presence (</span><span class="c5"><a class="c0"
                                                                               href="https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerAdvertiser.java#L44">https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerAdvertiser.java#L44</a></span><span>)</span><span>:</span>


ServiceDiscovery discovery = getDiscovery();
            discovery.start();
            ServiceInstance si = getInstance();
            log.info(si);
            discovery.registerService(si);


2. Another service - on another host or in another JVM on the same machine tries to discover who is implementing the service (https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerFinder.java#L50):

<a href="#"

                                                                                                  name="3"></a>

instances = discovery.queryForInstances(serviceName);

The whole concept here is ridiculously simple - the service advertising its presence just stores a file with its whereabouts. The service that is looking for service providers just look into specific directory and read stored definitions.

In my example, the structure advertised by services looks like this (+ some getters and constructor - the rest is here: https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/model/WorkerMetadata.java):


public final class WorkerMetadata {
    private final UUID workerId;
    private final String listenAddress;
    private final int listenPort;
}


Source code

<p

    class="c8"><span>The above recipes are available in Curator library (</span><span class="c5"><a class="c0"
                                                                                                    href="http://curator.incubator.apache.org/">http://curator.incubator.apache.org/</a></span><span>). Recipes&rsquo;
usage examples are in my github repo at </span><span class="c5"><a class="c0"
                                                                   href="https://github.com/zygm0nt/curator-playground">https://github.com/zygm0nt/curator-playground</a></span>

Conclusion

<p
    class="c8"><span>If you&rsquo;re in need of a reliable platform for exchanging data and managing synchronization, and you need to do it in a distributed fashion - just choose Zookeeper. Then add Curator for the ease of using it. Enjoy!</span>


  1. image comes from: http://www.flickr.com/photos/jfgallery/2993361148
  2. all source code fragments taken from this repo: https://github.com/zygm0nt/curator-playground

An application developed for one of my recent projects at TouK involved multiple servers. There was a requirement to ensure failover for the system’s components. Since I had already a few separate components I didn’t want to add more of that, and since there already was a Zookeeper ensemble running - required by one of the services, I’ve decided to go that way with my solution.

What is Zookeeper?

Just a crude distributed synchronization framework. However, it implements Paxos-style algorithms (http://en.wikipedia.org/wiki/Paxos_(computer_science)) to ensure no split-brain scenarios would occur. This is quite an important feature, since I don’t have to care about that kind of problems while using this app. You just need to create an ensemble of a couple of its instances - to ensure high availability. It is basically a virtual filesystem, with files, directories and stuff. One could ask why another filesystem? Well this one is a rather special one, especially for distributed systems. The reason why creating all the locking algorithms on top of Zookeeper is easy is its Ephemeral Nodes - which are just files that exist as long as connection for them exists. After it disconnects - such file disappears.

With such paradigms in place it’s fairly easy to create some high level algorithms for synchronization.

Having that in place, it can safely integrate multiple services ensuring loose coupling in a distributed way.

Zookeeper from developer’s POV

With all the base services for Zookeeper started, it seems there is nothing else, than just connect to it and start implementing necessary algorithms. Unfortunately, the API is quite basic and offers files and directories abstractions with the addition of different node type (file types) - ephemeral and sequence. It is also possible to watch a node for changes.

Using bare Zookeeper is hard!

Creating connections is tedious - and there is lots of things to take care of. Handling an established connection is hard - when establishing connection to ensemble, it’s necessary to negotiate a session also. During the whole process a number of exceptions can occur - these are “recoverable” exceptions, that can be gracefully handled and not break the connection.

    class="c8"><span>So, Zookeeper API is hard.</span></p><p class="c1"><span></span></p><p class="c8"><span>Even if one is proficient with that API, then there come recipes. The reason for using Zookeeper is to be able to implement some more sophisticated algorithms on top of it. Unfortunately those aren&rsquo;t trivial and it is again quite hard to implement them without bugs.</span>

And since distributed systems are hard, why would anyone want another difficult to handle tool?

Enter Curator

<p
    class="c8"><span>Happily, guys from Netflix implemented a nice abstraction for dealing with Zookeeper internals. They called it Curator and use it extensively in the company&rsquo;s environment. Curator offers consistent API for Zookeeper&rsquo;s functionality. It even implements a couple of recipes for distributed systems.</span>

File read/write

<p
    class="c8"><span>The basic use of Zookeeper is as a distributed configuration repository. For this scenario I only need read/write capabilities, to be able to write and read files from the Zookeeper filesystem. This code snippet writes a sample json to a file on ZK filesystem.</span>

<a href="#"
                                                                                                  name="0"></a>

EnsurePath ensurePath = new EnsurePath(markerPath);
ensurePath.ensure(client.getZookeeperClient());
String json = “...”;
if (client.checkExists().forPath(statusFile(core)) != null)
     client.setData().forPath(statusFile(core), json.getBytes());
else
     client.create().forPath(statusFile(core), json.getBytes());


Distributed locking

Having multiple systems there may be a need of using an exclusive lock for some resource, or perhaps some big system requires it’s components to synchronize based on locks. This “recipe” is an ideal match for those situations.

ref="#"
                                                                                    name="b0329bbbf14b79ffaba1139881914aea887ef6a3"></a>


lock = new InterProcessSemaphoreMutex(client, lockPath);
lock.acquire(5, TimeUnit.MINUTES);
… do sth …
lock.release();


 (from https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/LockingRemotely.java)

Sevice Advertisement

<p

    class="c8"><span>This is quite an interesting use case. With many small services on different servers it is not wise to exchange ip addresses and ports between them. When some of those services may go down, while other will try to replace them - the task gets even harder. </span>

That’s why, with Zookeeper in place, it can be utilised as a registry of existing services.

If a service starts, it registers into the ServiceRegistry, offering basic information, like it’s purpose, role, address, and port.

Services that want to use a specific kind of service request an access to some instance. This way of configuring easily decouples services from their configuration.

Basically this scenario needs ? steps:

<span>1. Service starts and registers its presence (</span><span class="c5"><a class="c0"
                                                                               href="https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerAdvertiser.java#L44">https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerAdvertiser.java#L44</a></span><span>)</span><span>:</span>


ServiceDiscovery discovery = getDiscovery();
            discovery.start();
            ServiceInstance si = getInstance();
            log.info(si);
            discovery.registerService(si);


2. Another service - on another host or in another JVM on the same machine tries to discover who is implementing the service (https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/curator/WorkerFinder.java#L50):

<a href="#"

                                                                                                  name="3"></a>

instances = discovery.queryForInstances(serviceName);

The whole concept here is ridiculously simple - the service advertising its presence just stores a file with its whereabouts. The service that is looking for service providers just look into specific directory and read stored definitions.

In my example, the structure advertised by services looks like this (+ some getters and constructor - the rest is here: https://github.com/zygm0nt/curator-playground/blob/master/src/main/java/pl/touk/model/WorkerMetadata.java):


public final class WorkerMetadata {
    private final UUID workerId;
    private final String listenAddress;
    private final int listenPort;
}


Source code

<p

    class="c8"><span>The above recipes are available in Curator library (</span><span class="c5"><a class="c0"
                                                                                                    href="http://curator.incubator.apache.org/">http://curator.incubator.apache.org/</a></span><span>). Recipes&rsquo;
usage examples are in my github repo at </span><span class="c5"><a class="c0"
                                                                   href="https://github.com/zygm0nt/curator-playground">https://github.com/zygm0nt/curator-playground</a></span>

Conclusion

<p
    class="c8"><span>If you&rsquo;re in need of a reliable platform for exchanging data and managing synchronization, and you need to do it in a distributed fashion - just choose Zookeeper. Then add Curator for the ease of using it. Enjoy!</span>


  1. image comes from: http://www.flickr.com/photos/jfgallery/2993361148
  2. all source code fragments taken from this repo: https://github.com/zygm0nt/curator-playground